Graph Databases
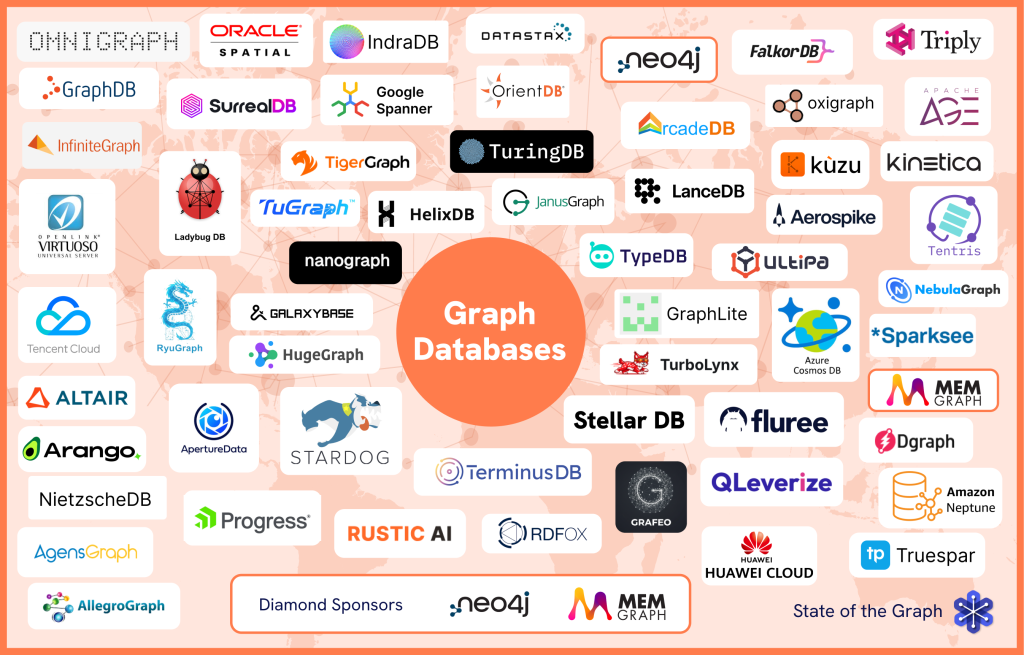
Graph database systems store and query data as graphs, treating nodes and relationships as first-class citizens. The State of the Graph database catalog offers a single access point for browsing, comparing, and choosing the offering that is right for your needs.
We split our graph database catalog into two groups in this sheet: the main table lists current, mainstream graph databases, while a later section labeled “Legacy, niche, and graph-adjacent databases (extended list)” captures older, more specialized, or graph-adjacent offerings for completeness.
Our Sponsors
Memgraph
Diamond sponsor
Memgraph is a high-performance, in-memory graph database built for real-time AI context and graph analytics. It serves as the graph engine for GraphRAG pipelines, AI memory systems, and agentic workflows, delivering sub-millisecond multi-hop traversals with full provenance for systems that need structured, connected context alongside semantic search. The same architecture powers real-time graph analytics across fraud detection, network analysis, infrastructure monitoring, and other operational use cases.
Neo4j
Diamond sponsor
Neo4j is the knowledge layer for enterprise AI. Powered by the Neo4j Graph Intelligence Platform, Neo4j connects organizational data with humans and AI systems, surfacing not just relationships, but how and why they exist. The result is AI that is accurate, explainable, and governable. Built to integrate with everything. Proven by 84 of the Fortune 100 and supported by the world’s largest graph community, Neo4j helps organizations move AI from pilot to production.
To be included, an offering has to meet three criteria:
- First-class graph model: It exposes a clear property graph or RDF model, with nodes (vertices) and edges (relationships) as core structures, and full support for CRUD (Create, Read, Update, Delete) operations via a graph API / query language.
- First-class graph querying: It supports graph-aware query languages or APIs (for example, Cypher, SPARQL, Gremlin, GQL, or an equivalent), not just ad-hoc joins or custom code on non-graph storage.
- Deployable product: It has a clear deployment path as open source or commercial, self-managed, managed in the customer’s cloud, or SaaS, suitable for real-world use rather than only experiments.
The table summarizes these products across key dimensions such as graph model, storage and distribution, workload focus, transactions, scalability and high availability, query languages, tooling and ecosystem, availability and deployment options, marketplace presence, and product status, so you can quickly see where each one fits and which are worth deeper evaluation.
Tech Professionals | Analysts and Investors | Vendors and Builders
Please note: You need to create an account in order to access this content.
The table summarizes these tools across key dimensions so you can quickly see where each product fits and which merit a deeper look.